

On our homepage FAQ, under the heading ‘What buyers ask us first’, there is one question we keep open by default: ‘How do you keep AI from making things up?’. Buyers ask it whether they run a legal publisher, a fintech product or an internal knowledge base, and they all want the same thing: an AI chatbot that doesn’t hallucinate on their own business data. This article is the long answer, based on how we built Edtek Chat, our own product, and the AAAi Chat Book for the American Arbitration Association on top of it.
A very short summary: yes, an AI chatbot can be built that never invents a source, if grounding is enforced in code, not requested in a prompt. Four rules do most of the work: answer only from retrieved passages, let retrieval (not the model) number the citations, strip any reference to a passage that was not retrieved, and do not call the model at all when retrieval finds nothing. Then measure: 30 clean test questions only prove a failure rate below roughly 10%.
Can you build an AI chatbot that doesn’t hallucinate on your own data?
Partly. Some failure modes can be removed entirely by the architecture: a citation to a document that does not exist, or an answer generated when nothing relevant was found. Others can only be made unlikely and measured: a real passage cited for a sentence it does not quite support, or two sources blended into a claim neither of them makes.
Most vendors do not make this distinction, and the market shows the cost. In 2024 a team from Stanford tested the AI research tools of LexisNexis and Thomson Reuters, products built on retrieval over curated legal databases, whose makers had said that retrieval ‘avoids’ hallucinations (Thomson Reuters) or promised ‘hallucination-free’ citations (LexisNexis); Casetext, since acquired by Thomson Reuters, had said it ‘eliminates’ them. Each of them hallucinated between 17% and 33% of the time. These are not toy chatbots over a folder of PDFs.
Thus, I don’t think ‘zero hallucination’ or ‘hallucination-free’ is an honest promise for any system that writes free text. Even a 2026 paper on enterprise AI titled Zero Hallucination, by Construction treats hallucination as ‘a containable failure mode rather than an eliminable one’: its ‘zero’ is something the surrounding system enforces, not a property of the model. ‘It cannot cite what it did not retrieve, it does not answer when it found nothing, and here is the measured rate for everything else’ is honest. That is the one we make.
Why do AI chatbots hallucinate on internal data?
Because a language model is trained to be helpful, and when the right passage is missing it produces the most plausible text it can. On business data the plausible answer is often the industry-typical one, not yours.
The most instructive case I know is not from law. In February 2024 the British Columbia Civil Resolution Tribunal decided Moffatt v. Air Canada. The airline’s chatbot told a customer he could apply for a bereavement fare retroactively; the airline’s own policy page said the opposite. In effect, Air Canada argued that the chatbot was a separate entity responsible for its own words. The tribunal rejected this and held the airline liable. The correct answer was on the same website, and the chatbot still invented a reasonable-sounding policy.
In my practice, the causes behind such failures repeat:
- Retrieval misses. The right passage exists but did not come back (bad chunking, different wording, a threshold set too high). The model fills the gap from memory.
- Retrieval returns the nearest thing. Nothing relevant exists, but a vector index always returns something. The model treats loosely related text as support.
- The model writes the citations. Then it can cite a passage that was never in its context, or attach the right number to the wrong sentence.
- The prompt is the only guard. ‘Answer only from the context’ works most of the time. ‘Most of the time’ is not a property you can put in a contract.
- Follow-up questions drift away from the library and into the model’s own knowledge.
None of them is fixed by choosing a bigger model.
How do you enforce grounding in code, not in the prompt?
By making the dangerous outcomes impossible for the program, whatever the model generates. A prompt is a request; code is a constraint. This is how Edtek Chat works, as documented on the product site:
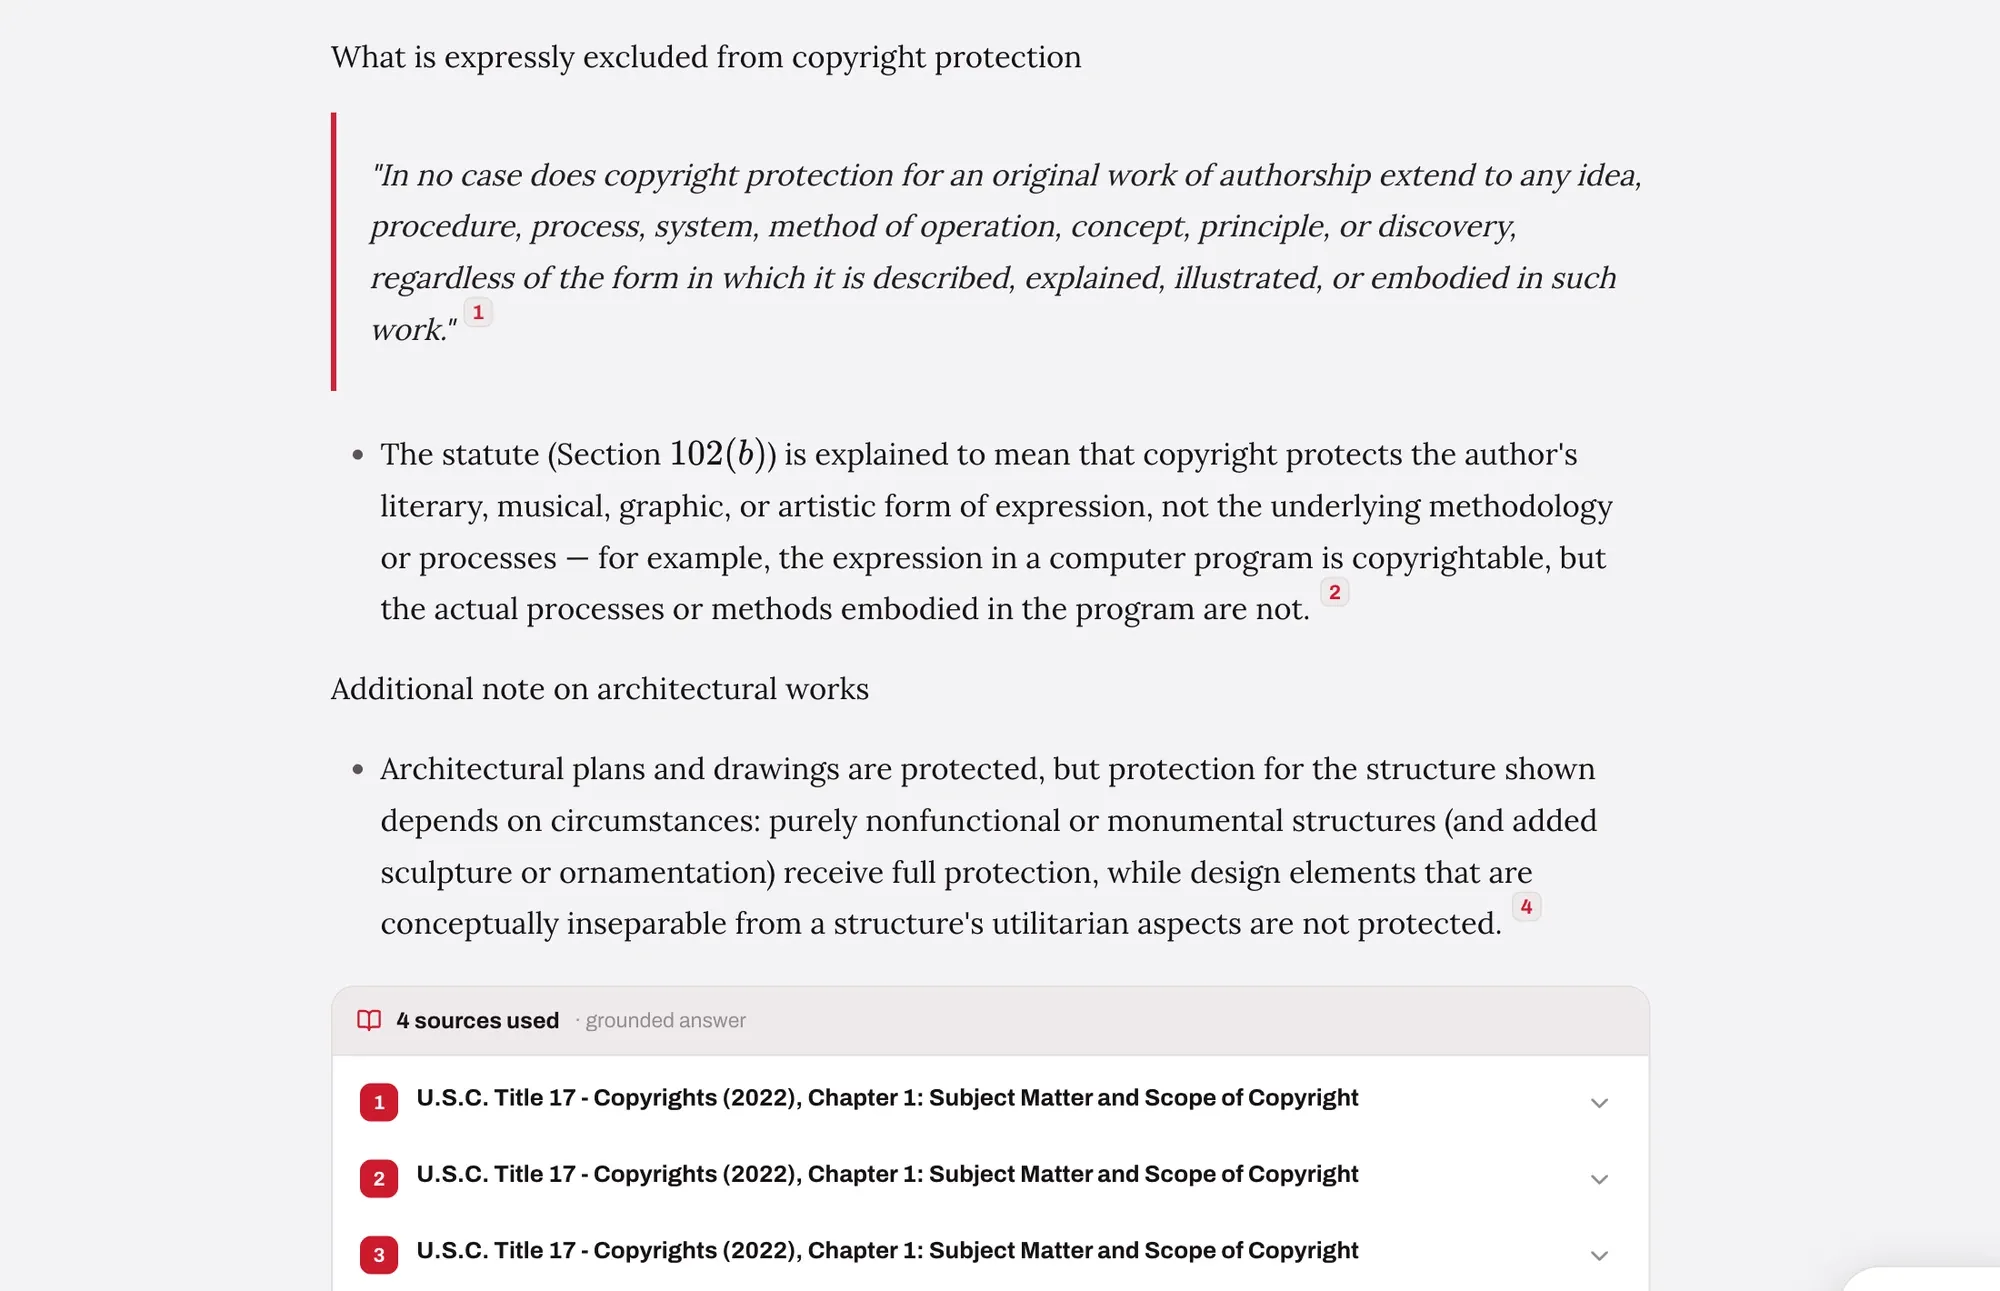
- Citation numbers are assigned by retrieval, bound to the retrieved passages for the whole turn. The model only references them.
- References to anything not retrieved are stripped before the answer reaches the screen. A reader cannot click a citation that leads nowhere.
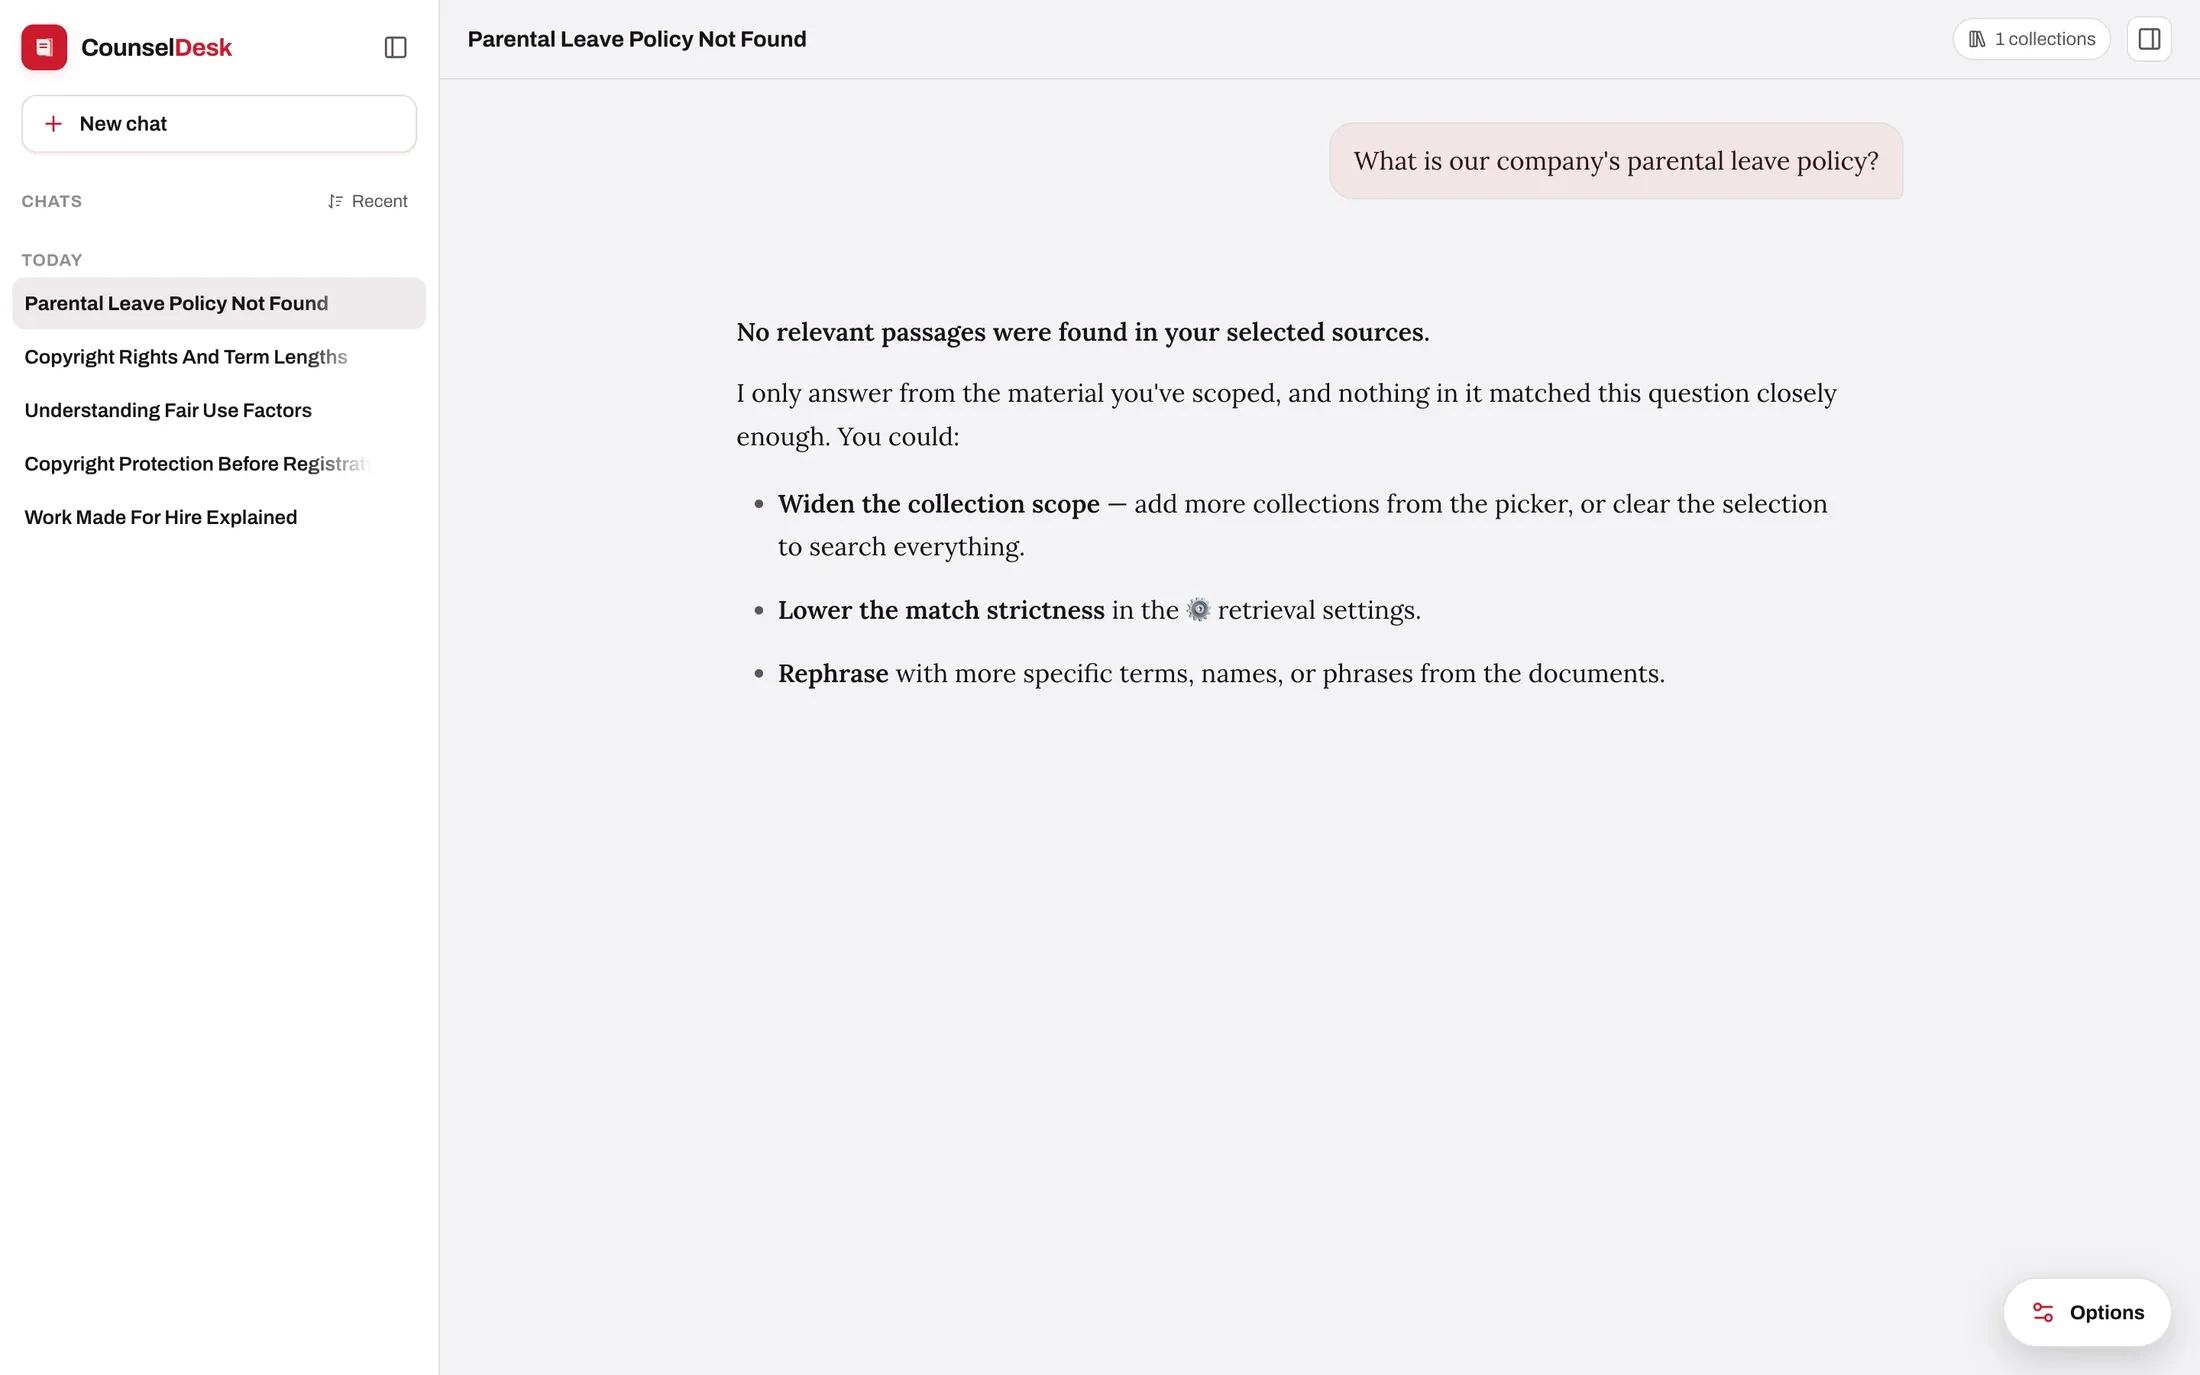
- No passages, no model call. If nothing in the selected sources matches a first question, the answering model is never called.
- Retrieved passages always reach the prompt, even if a custom prompt forgets them, so a configuration mistake cannot leave the model answering from memory.
- A deployment can only search the collections it was granted.
Can a document assistant cite a source for every answer? Yes, in the sense that matters: every answer from the library is generated only from retrieved passages, so there is always something real to cite, and when retrieval finds nothing the reader gets a refusal instead of an uncited guess. The one exception by design is a follow-up answered from the conversation so far, where citations are forbidden rather than invented. Whether each sentence carries the right citation is the part you measure.
Everything else sits in the right column below, where the tools are probabilistic and therefore measured.
| Enforced in code | Made unlikely, and measured | |
|---|---|---|
| Citations | A citation can only point at a passage that was really retrieved | That the cited passage really supports the sentence next to it |
| Empty retrieval | No passages and no prior conversation: no answer is generated | That every retrieved passage is genuinely on point (optional relevance pass) |
| Prompt | Retrieved passages always reach the model | That the model stays inside the sources it was given (optional verification pass) |
| Scope | Only granted collections are searched | That the answer is complete, not only correct |
| Evidence | The reader opens the cited source beside the answer, with the passage highlighted | Overall answer quality, tracked by the evaluation suite |
The relevance pass is a second model that keeps a passage only on an explicit ‘yes’; the verification pass re-reads the draft against its citations and corrects it, at the price of live streaming. Both are off by default, because each adds a model call, and whether that is worth it depends on the stakes.
I find this split useful far beyond our own product. When I look at someone else’s system, I first ask which of its anti-hallucination claims live in which column. Usually everything is in the right one, and nobody measures it. More on retrieval in our RAG implementation guide and, for statutes and case law, in RAG for legal documents; on citation checks, in citation verification for legal AI.
When should the assistant refuse to answer?
Whenever retrieval did not find support, and the refusal should be a rule in code, not a decision of the model. A model asked to write a refusal is trusted to refuse. Usually it does. Occasionally it does not.
In practice there are three states, not two. Edtek scores the passages that survive retrieval into a good match, a weaker match, or nothing:
- Good match: the answer is shown normally.
- Weaker match: the answer is still shown, with a visible ‘lower confidence’ label. It is a signal to check the citations more carefully, not a silent filter.
- Nothing: on a first question, a fixed refusal with suggestions (widen the scope, rephrase in the documents’ terms). On a follow-up (with conversation history enabled), the model may answer from the conversation so far, with outside knowledge and citations forbidden.
Of course, refusals have a price: a strict system declines some questions a looser one would answer correctly. However, for a professional audience this trade is almost always right. A lawyer who receives one invented rule stops trusting the other ninety-nine correct answers.
The AAAi Chat Book, launched in January 2025, is built on this design: answers only from retrieved passages, citations from retrieval, and an honest ‘no answer’ when the corpus has none. Four editions are live today, and the tool has handled thousands of questions from the public about arbitration and mediation.
A breakthrough in making arbitration more efficient, accessible and fair.
How do you measure the hallucination rate, and how many test questions do you need?
Run a fixed set of your own questions through the same pipeline your users hit, and count the failures. Then size the set honestly: with zero failures in n questions you can only claim, at 95% confidence, a rate below about 3/n, so 30 clean questions prove under 10% and 300 prove under 1%. Most teams ignore this second part.
A useful starting set has three kinds of question (our protocol describes it in detail): a single findable answer, an answer that combines two or more passages, and reasonable questions your library does not answer. The last group decides everything: a fluent system cannot pass it by being fluent.
Score both sides of it. A system that refuses everything never hallucinates either, so report two numbers, not one: unsupported answers (including any answer to a question the library cannot answer), and refusals on questions it can. A refusal on an answerable question is not a safe outcome; it is a failure, usually of retrieval.
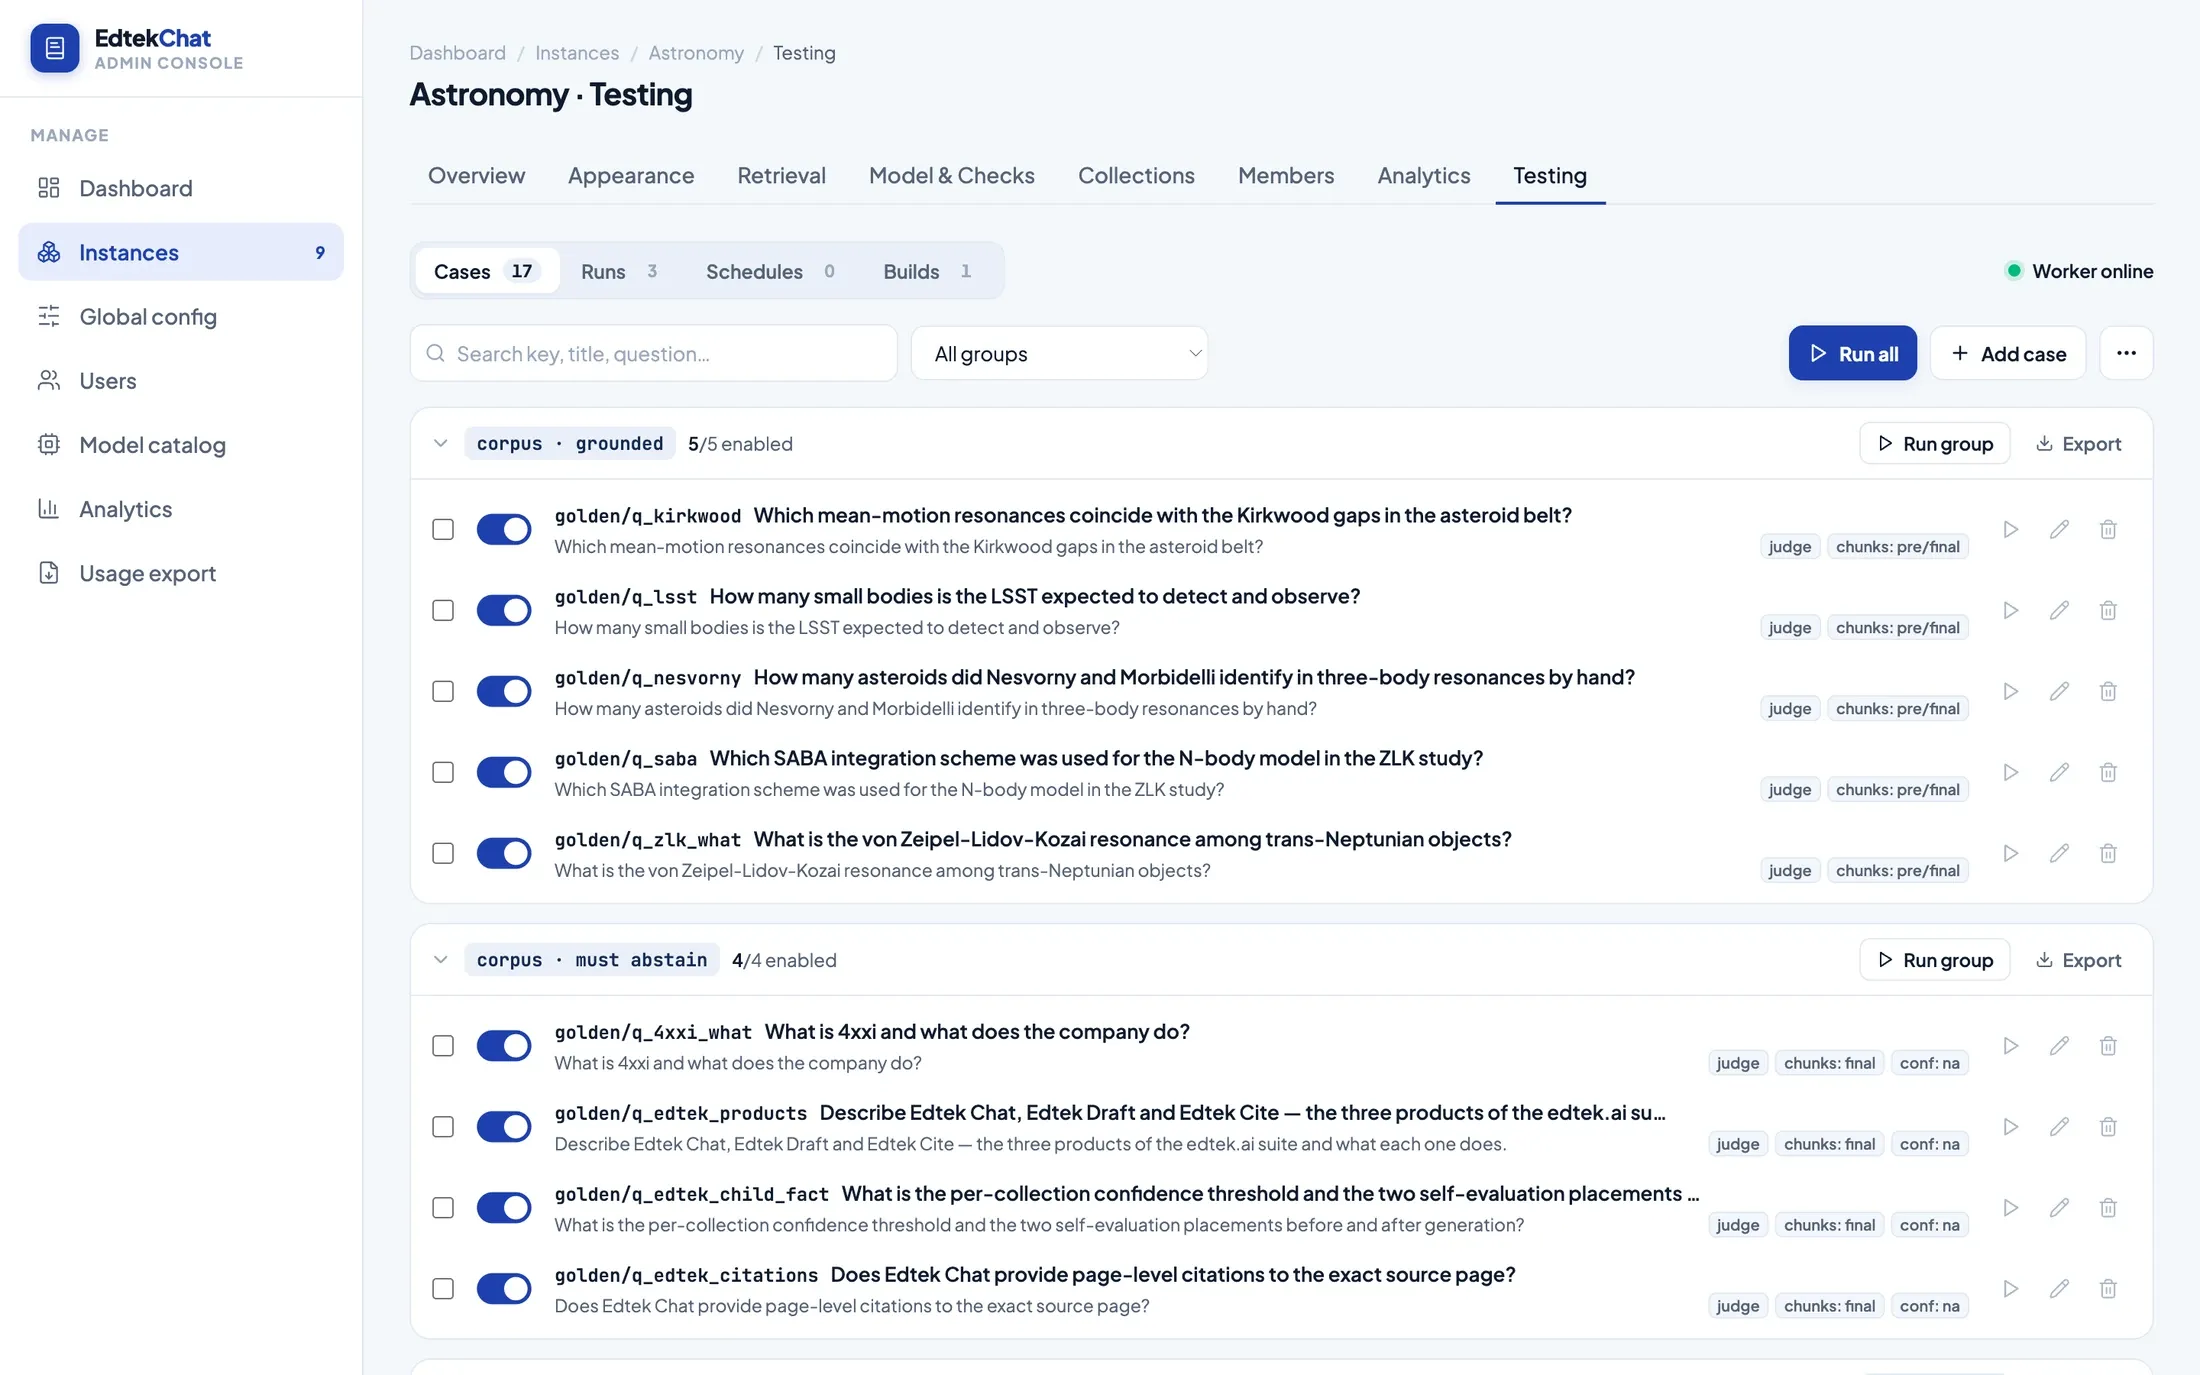
Each case should be judged by more than one model’s opinion. In the Edtek evaluation suite a case fails on a judge score against a reference answer, on rules (text that must or must not appear), on retrieval assertions, on confidence (a question that must come back unanswered), or on a latency ceiling. A case can be repeated up to ten times and folded to the worst outcome, so an intermittent failure cannot pass by luck. An LLM judge alone is a soft signal; with deterministic checks it becomes a test.
Now the statistics, which almost nobody shows. If you run n questions and see zero failures, the upper bound of the 95% confidence interval for the true failure rate is approximately 3/n. This is the ‘rule of three’ from Hanley and Lippman-Hand (JAMA, 1983), originally written for medical studies that observe zero adverse events.
| Clean test questions (zero failures) | What you can honestly claim (95% upper bound) |
|---|---|
| 30 | failure rate below ~10% |
| 100 | below ~3% |
| 300 | below ~1% |
| 1,000 | below ~0.3% |
So when a vendor says ‘below 1%’ after a demo of twenty questions, the evidence does not support the claim, whatever the true rate is.
The second point is where the questions come from. In our benchmark of commercial and open-source LLMs published in Scientific Reports this year (a classification task from dynamical astronomy), the models’ errors were not random: they concentrated on the same ambiguous, borderline cases where a human expert also makes mistakes (I wrote up what the benchmark means for product work separately). I would expect the same in a document assistant: weight the test set towards hard and ambiguous questions. Writing hundreds of them by hand is why most teams never do it. In Edtek the test builder drafts cases from the documents, including deliberately unanswerable ones, verifies them through the real pipeline, and saves them switched off until a person enables them.
Finally, keep a baseline. Any change of model, threshold, prompt or documents can silently make answers worse; a run compared against a baseline turns that from an opinion into a diff. More on this in how evaluation works in Edtek.
Which enterprise AI chatbots minimise hallucinations on complex internal data?
The ones that enforce grounding in code and pass a test on your own questions, not on the vendor’s demo. We build one of the options, Edtek Chat, so I will not pretend to a neutral ranking; however, the eight questions below work against us too:
- Who assigns citation numbers? If the model writes them, dead or misattached citations are possible.
- Does a citation open the page, with the passage highlighted, or only the file?
- What happens on empty retrieval? Is the answering model called at all?
- Is the ‘I don’t know’ answer fixed or generated?
- Can you see which passages were retrieved but not used, with their scores?
- Does the evaluation run the production pipeline, or a separate demo path?
- Can you run your own questions, including unanswerable ones, and get a pass rate, latency and cost per answer?
- Where do the documents and the inference live? Your cloud, their cloud, or a model provider you did not choose.
The options fall into four groups. A general-purpose assistant pointed at a folder is quick, cheap and fine for internal drafts, but rarely gives you control over the first three questions. Vertical products from large content vendors own excellent content, yet the Stanford study shows that owning the content is not the same as enforcing grounding. A framework you assemble yourself can pass every question, if your team implements every rule and the test suite. And a product built around these rules, such as Edtek Chat, passes them out of the box and runs on your infrastructure with your own models (OpenAI, Azure OpenAI, OpenRouter or any OpenAI-compatible endpoint).
Build, buy or license?
License if your content is the product and you need it live in months; build if the assistant is one feature inside a larger system that only you understand. Buying a hosted tool is the right answer only when the stakes are low.
| License Edtek | Build custom with us | Hosted SaaS assistant | |
|---|---|---|---|
| Grounding rules | Built in | Implemented for your system | Depends on the vendor; ask the checklist |
| Who owns what | Non-exclusive licence to the software; your content stays yours | Code, prompts and eval sets belong to you | The vendor’s platform |
| Infrastructure | Can run fully on your premises | Wherever you need it | Vendor cloud |
| Price | On request | Our standard rate, $200/h | Per seat or per usage |
| Fits when | You publish or own a large library | AI is part of your existing product | Internal, low-stakes use |
The two can be combined. A legal publisher we work with took Edtek rather than starting from scratch, and we integrated it into their own platform and infrastructure. If your case looks like this, our article on AI for professional publishers goes into more detail, and integrating an LLM into existing software covers the build side.
When don’t you need any of this?
When nobody acts on the answer without checking it anyway. An internal assistant that helps people find a document, brainstorm, or summarise a file they have open does not need a refusal path and a 300-question suite. A good hosted assistant is enough, and I would tell you so on a call.
You also do not need it if the whole library fits into the model’s context window, if the questions require judgement beyond the documents (advice, negotiation, strategy), or if you do not own the content and cannot license it. In the last case, the problem is legal, not technical.
And do not hire us for a marketing chatbot where creativity is the point, or for the cheapest build regardless of accuracy. We are a small senior team at $200/h, and our strength is the boring part: rules in code and measurement before launch.
Your assistant already hallucinates?
Then find out where before rewriting anything. Our audit of existing AI systems (part of our AI opportunity audit) takes two weeks and costs $5–10k, fixed, with a full money-back guarantee; if you sign a project with us within 60 days, the fee is credited in full towards it. We check security, robustness, technology choices, automation and running costs (for an assistant, also grounding and retrieval), and tell you which guarantees live in code and which only in a prompt. The problems we see most often are not exotic: weak security and architecture, a ‘zoo’ of stacks, and ready-made automation (on github and elsewhere) nobody switched on.
If you are starting from a library rather than a broken system, the quickest way to judge grounding is to watch it refuse. Book an Edtek demo and ask it something your documents do not cover. Or book a call with me and bring your thirty hardest questions, including the ten your library cannot answer.
Sources
- Magesh V. et al. Hallucination-Free? Assessing the Reliability of Leading AI Legal Research Tools. arXiv:2405.20362, 2024. arxiv.org/abs/2405.20362
- Raduta B., Velicu H., Preda A., Chiricescu S. Zero Hallucination, by Construction: Hallucination-Aware Layered Oversight for Trustworthy Enterprise AI. arXiv:2607.17883, 2026. arxiv.org/abs/2607.17883
- Moffatt v. Air Canada, 2024 BCCRT 149, British Columbia Civil Resolution Tribunal. decisions.civilresolutionbc.ca
- Hanley J. A., Lippman-Hand A. If nothing goes wrong, is everything all right? Interpreting zero numerators. JAMA 249(13):1743–1745, 1983. doi.org/10.1001/jama.1983.03330370053031
- Smirnov E., Carruba V. Evaluating multimodal commercial and open-source large language models for dynamical astronomy: a benchmark study of resonant behavior classification. Scientific Reports 16, 10785, 2026. doi.org/10.1038/s41598-026-45926-y
- Edtek Chat documentation: grounded answers, evaluation.